
 ">WeChat
# The source view –The game source.
#python3用于爬取ip代理地址,程序暂未完善,没有有做自动翻页
import requests
import parsel
import time
def check_ip(proxies_list):
“””检测ip的方法”””
headers = {‘User-Agent’: ‘Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/79.0.3945.79 Safari/537.36’}
can_use = []
for proxy in proxies_list:
try:
response = requests.get(‘http://www.baidu.com’, headers=headers, proxies=proxy, timeout=0.1) # 超时报错
if response.status_code == 200:
can_use.append(proxy)
except Exception as error:
print(error)
return can_use
import requests
import parsel
# 1、确定爬取的url路径,headers参数
base_url = ‘https://www.kuaidaili.com/free/intr’
⁇ User-Agent’: ‘Mozilla/5.0; Win64; x64) AppleWebKit/5337 (KHTML, like Gecko) Chrome/79.39.45.79 Safari/537′} #2, sending request — send requests for simulation browsers send data requistes.get=requests.Get=headers) Data = creation.text #print(data) # open a ip.txt file to record file = open (`ip.txt’, ‘a+’, encoding=’utf-8′) #a+ (additionalable if the document is not available) #3, parsel to Selecor object, which has an xpath method for processing converted data # 3, 1 Convert python interactive data type # html_data = parsel. Selector (data) # 3, 2 Parse_list = html_data.xpath (‘/table[@class=”table table-ckered table-striped”]/ tbody/tr’) # Return to Selector object # print(pars_list) # Free IP {the protocol: “port” # # # cycle round time, secondary extracts ⁇ [for in_list: papers_diment=}[4]/text()’).extract_first()
ip_num = tr.xpath(‘./td[1]/text()’).extract_first()
port_num = tr.xpath(‘./td[2]/text()’.extract_first()#print (http_type, ip_num, port_num) # Write to txt files file file file.write(`)file.write(`port_num) file.write(`n’) # Build proxy ip dictionary[http_type] = ip_num + ‘: ‘+ port_num # prixies_dec) program_list.append (products_list) print(“Retrieved proxy ip:”, llen (proxies_list), file.close()
未经允许不得转载:萌萌Apprentissage » Python for crawling over ip proxy address


 Python batches to extract mainstream search engine pictures
 Python's word crawling across 100 degrees.
 PythonTaiichi Taipei Artificial Intelligence Tensoflow Graphic Processing
 Selenium with Tor Browser using Python
 I'm gonna get you a new one, shell.cloud.google on the line.
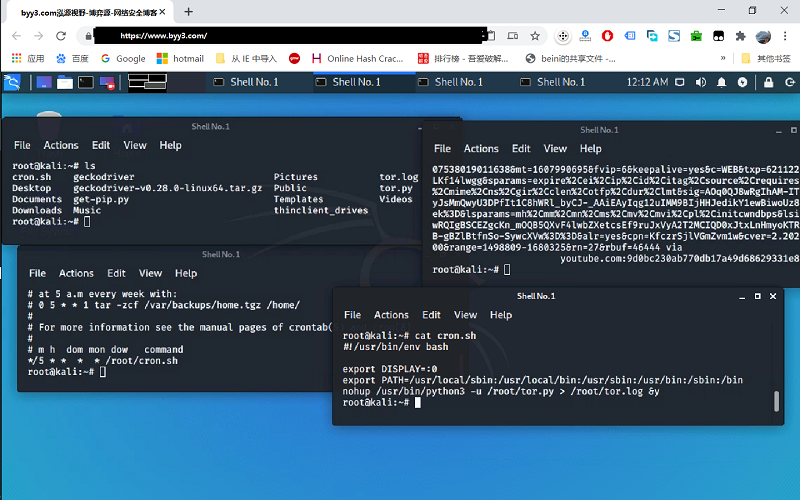 run crontab with python selenium tor browser display in linux

